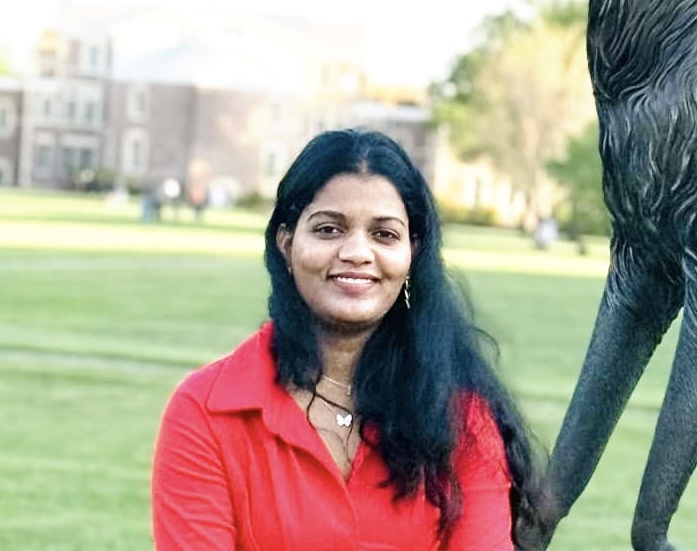
Sailaja Morrennagari, AI/ML and MLOps Engineer
AI/ML Engineer · Generative AI · MLOps

SailajaMorrennagari

I take machine learning from notebook to production. 6+ years building data pipelines, training and inference systems, RAG and agentic AI, and the MLOps that keeps them reliable on AWS and Kubernetes.

Open to MLOps, ML Platform, Data Engineering and Applied AI roles · Authorized to work in the U.S.
llmops-platform · gateway
$ curl -X POST :8000/v1/generate \
    -d '{"prompt":"Who is Sailaja?"}'

{
  "output": "An AI/ML engineer who ships
     RAG, agents and MLOps to production.",
  "skills": ["PyTorch", "Kubernetes",
             "LangChain", "AWS"],
  "experience_years": 6,
  "status": "open_to_work"
}
# llm_requests_total{status="ok"} 1
$ 
Impact

Results from production work

RAG65%faster clinical document search across 10K+ documents
CI/CD40%shorter deployment cycles with MLflow, Docker and Kubernetes
Modeling70 → 82.6%model accuracy in clinical risk scoring (+12.6 points)
Spark35%faster batch processing through partitioning and tuning
DataPipelinesKafka, PySpark, Airflow
TrainModelsPyTorch, TensorFlow, MLflow
ServeDeployDocker, Kubernetes, SageMaker
WatchMonitorPrometheus, Grafana, data checks
Selected work

Projects, told as case studies

FeaturedAgentic RAG

Local Agentic Copilot

Problem

Cloud copilots send private documents off-device and often answer without showing where facts came from.

Approach

A fully local copilot on Ollama (Qwen3) with Researcher, Coder and Reviewer agents, deterministic guardrails and a bounded self-correction loop.

Evaluation

Reproducible benchmarks compare Top-1 and Top-3 retrieval across semantic, BM25, hybrid and reranked setups, with failure analysis driving each iteration. On a 47-question benchmark, dense and BM25 each reached 91.5% Top-1 but failed on different questions; hybrid fusion (RRF) reached 100% (47/47), and a cross-encoder reranker added ~50 ms/query with no further gain.

Query
→
Dense searchSentence-Transformers
+
BM25keyword
→
Hybrid fusion
→
Cross-encoderrerank
→
Researcher · Coder · Reviewerself-correction loop
→
Answerpage-aware citations
PythonOllamaQwen3ChromaDBBM25Cross-Encoder
KubernetesLLMOps

LLMOps Platform

A production-style LLM platform on Kubernetes, with every design decision backed by measurements. A FastAPI gateway (API keys, rate limits, circuit breaker, streaming, load shedding, Prometheus metrics) fronts a self-hosted Qwen2.5-3B and a hybrid-retrieval RAG service. Load tests found a probe bug that restarted healthy pods: fixing it cut stress-test errors from 30% to 0%. RAG answers carry gateway-verified citations, and a prompt change raised citation accuracy from 40/47 to 47/47; layered guardrails let 0 of 12 red-team attacks through.

Client
→
Gatewayguardrails · /v1/ask
→
RAG serviceBM25 + dense
→
OllamaQwen2.5-3B
KubernetesHelmFastAPIRAGGuardrailsPrometheusLocust
Generative AI

Enterprise RAG Chatbot

Context-aware answers over enterprise documents, with ingestion, retrieval and LLM orchestration tuned through prompt engineering and embedding optimization.

Docs
→
Embeddings
→
FAISS
→
LLM
LangChainFAISSEmbeddings
Reinforcement learning

Deep RL for Stock Trading

A custom trading environment on real market data with PPO, A2C and Double DQN agents. Overfitting was reduced through architecture tuning and reward shaping.

PythonTensorFlowPPOA2CDouble DQN

Also on GitHub: face recognition with OpenCV, fake-review detection with NLP, credit-card fraud detection and image classification. See all repositories

Experience

From data pipelines to production AI

Jun 2025 – Present
UnitedHealth Group

AI/ML Engineer (Contract)

  • Deployed ML training and inference workflows for clinical risk scoring on AWS SageMaker, improving accuracy from 70% to 82.6%.
  • Built RAG applications with LangChain and FAISS, cutting clinical document search time by 65% across 10K+ documents.
  • Built Kafka, PySpark and Airflow pipelines supplying high-volume data to ML workloads.
  • Standardized model packaging and CI/CD with MLflow, Docker, Kubernetes and GitHub Actions, reducing deployment cycle time by 40%.
  • Instrumented ML services with Prometheus and Grafana for monitoring, alerting and root-cause analysis.
Mar 2022 – Dec 2023
Tata Consultancy Services

Data Scientist

  • Built and evaluated classification and predictive models with feature engineering and validation.
  • Cut data preparation time by 30% and report turnaround by 40% with recurring Snowflake queries.
  • Developed ML-ready dataset pipelines with AWS Glue, S3 and PySpark.
Jun 2018 – Feb 2022
Hexaware Technologies

Data Engineer

  • Developed distributed PySpark and SQL pipelines for high-volume data.
  • Reduced batch-processing time by 35% through partitioning and query optimization.
  • Implemented data-quality rules that reduced data defects by 30%.
Toolbox

Skills

ML infrastructure

MLflowDockerKubernetesGitHub ActionsSageMakerModel servingFastAPILLM gateways

Generative AI

LLMsRAGLangChainFAISSChromaDBAgentsLLM evalOllama

Machine learning

PyTorchTensorFlowScikit-learnXGBoost

Data systems

PySparkKafkaAirflowDelta LakeSnowflakeHadoop

Cloud

SageMakerS3GlueRedshiftEMR

Observability

PrometheusGrafanaGreat ExpectationsPyTest
Education

Degrees and certifications

May 2025M.S. Computer Science (Machine Learning)University of South Dakota
2021Master of Computer ApplicationsDr. Ambedkar Institute of Technology
2018B.Sc. Mathematics, Physics & CSSri Venkateswara University
AWS Certified Solutions Architect – Associate IBM Generative AI (LangChain RAG) ML & Deep Learning – REGEX Software LeetCode · 400+ problems
Contact

Let’s build something that ships.

Hiring for MLOps, ML platform, data engineering or applied AI? I’d be glad to hear from you.

morrennagarisailaja@gmail.com